Results
Historical results snapshot generated from committed benchmarks/results/*.csv files before the newer statistical and preparation-timing metrics were added. Run bsb report to see the current extended schema. No missing measurement has been inferred. See Reproduce and verify.
Quantization trade-offs (x86_64)
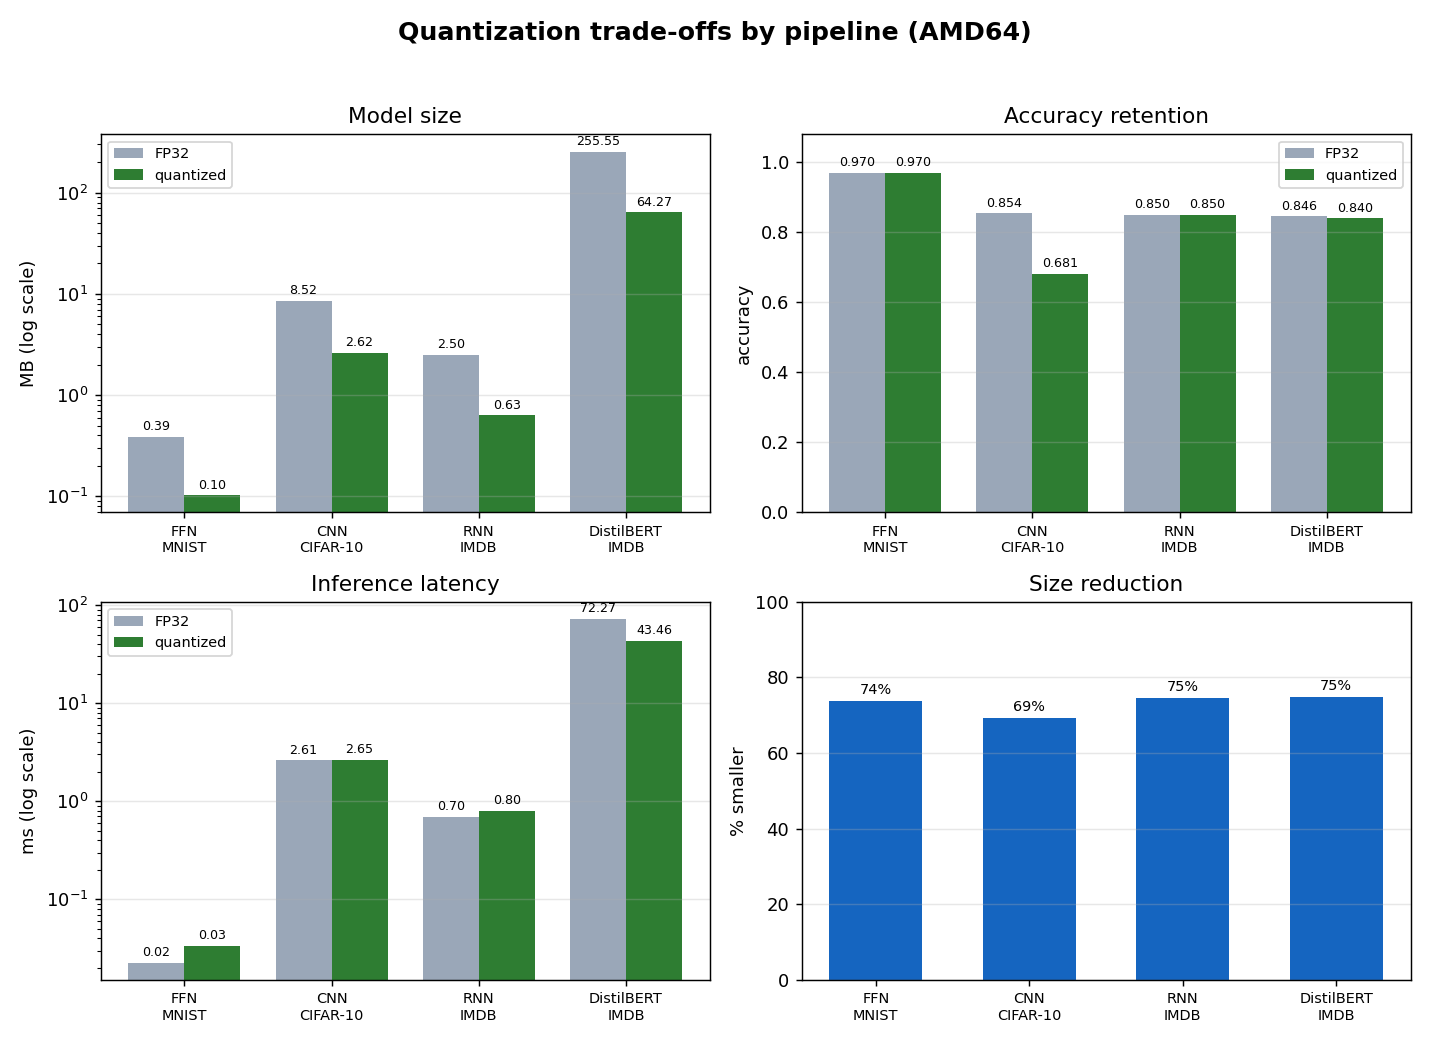
Per-variant detail
| pipeline | modality | runtime | variant | arch | emulated | size_mb | accuracy | accuracy_ci95 | agreement | latency_ms_mean | size_reduction_% | latency_speedup_x | accuracy_delta |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| cnn_cifar10 | vision | tflite | fp32 | x86_64 | False | 8.522 | 0.854 | ±2.2 pts | 1.0 | 1.993 | 0.0 | 1.0 | 0.0 |
| cnn_cifar10 | vision | tflite | int8 | x86_64 | False | 2.615 | 0.681 | ±2.9 pts | 0.699 | 2.144 | 69.3 | 0.93 | -0.173 |
| cnn_cifar10 | vision | tflite | fp32 | aarch64 | False | 8.522 | 0.854 | ±2.2 pts | 1.0 | 2.975 | 0.0 | 1.0 | 0.0 |
| cnn_cifar10 | vision | tflite | int8 | aarch64 | False | 2.615 | 0.688 | ±2.9 pts | 0.704 | 1.192 | 69.3 | 2.5 | -0.166 |
| distilbert_imdb | nlp | onnxruntime | fp32 | x86_64 | False | 255.549 | 0.846 | ±3.2 pts | 1.0 | 99.092 | 0.0 | 1.0 | 0.0 |
| distilbert_imdb | nlp | onnxruntime | int8 | x86_64 | False | 64.269 | 0.84 | ±3.2 pts | 0.954 | 54.521 | 74.9 | 1.82 | -0.006 |
| distilbert_imdb | nlp | onnxruntime | fp32 | aarch64 | False | 255.549 | 0.848 | ±3.1 pts | 1.0 | 61.767 | 0.0 | 1.0 | 0.0 |
| distilbert_imdb | nlp | onnxruntime | int8 | aarch64 | False | 64.269 | 0.834 | ±3.3 pts | 0.942 | 16.929 | 74.9 | 3.65 | -0.014 |
| ffn_mnist | vision | tflite | fp32 | x86_64 | False | 0.39 | 0.97 | ±1.1 pts | 1.0 | 0.022 | 0.0 | 1.0 | 0.0 |
| ffn_mnist | vision | tflite | int8 | x86_64 | False | 0.102 | 0.97 | ±1.1 pts | 0.998 | 0.012 | 73.7 | 1.84 | 0.0 |
| ffn_mnist | vision | tflite | fp32 | aarch64 | False | 0.39 | 0.97 | ±1.1 pts | 1.0 | 0.011 | 0.0 | 1.0 | 0.0 |
| ffn_mnist | vision | tflite | int8 | aarch64 | False | 0.102 | 0.971 | ±1.1 pts | 0.999 | 0.004 | 73.7 | 2.45 | 0.001 |
| rnn_imdb | sequence | tflite | fp32 | x86_64 | False | 2.498 | 0.85 | ±3.1 pts | 1.0 | 0.541 | 0.0 | 1.0 | 0.0 |
| rnn_imdb | sequence | tflite | dynamic_range | x86_64 | False | 0.635 | 0.85 | ±3.1 pts | 1.0 | 0.608 | 74.6 | 0.89 | 0.0 |
| rnn_imdb | sequence | tflite | fp32 | aarch64 | False | 2.498 | 0.85 | ±3.1 pts | 1.0 | 0.512 | 0.0 | 1.0 | 0.0 |
| rnn_imdb | sequence | tflite | dynamic_range | aarch64 | False | 0.635 | 0.85 | ±3.1 pts | 1.0 | 0.407 | 74.6 | 1.26 | 0.0 |
Notes
size_reduction_%is how much smaller the variant is than its FP32 original.latency_speedup_xis FP32 time divided by variant time, so above 1 means faster and below 1 means slower.accuracy_deltais the change in accuracy as a fraction (-0.173 means 17.3 percentage points lower).accuracy_ci95is the per-model Wilson 95% interval half-width. It cannot test a paired FP32/INT8 accuracy difference, because both variants classify the same evaluation examples. Historical rows lack the paired predictions needed for that test: a small difference does not prove equivalence.agreementis the share of test examples receiving the same predicted label.- The historical FP32/quantized rows are paired within their recorded hardware; newer results also pair using
run_idand store model SHA-256 hashes. The original x86/ARM64 models were trained separately, not byte-identical. Sizes use MiB (1,048,576 bytes); latency here measures model-only inference, not data preprocessing. - Rows with
emulated = Truecome from QEMU-emulated ARM64. Their absolute latency is not comparable to native runs, so treat it as a relative ratio only (see the methodology).